A computing cluster brings together several interconnected machines that function as a single system. This architecture, long reserved for scientific research and supercomputers, has become more accessible with the decrease in hardware costs and the explosion of data volumes. Companies use it for various needs, from intensive computing to service continuity.
Energy reporting obligation: what the European regulation changes for clusters
The articles dedicated to clusters often limit themselves to the technical mechanics. They overlook a regulatory framework that directly modifies the infrastructure choices of European companies.
Since the overhaul of the Directive (EU) 2023/1791 on energy efficiency and the adoption of the Delegated Regulation (EU) 2024/1364, data centers with an installed IT power exceeding 500 kW are required to report their energy performance indicators annually. The PUE (Power Usage Effectiveness), the WUE (Water Usage Effectiveness), the share of renewable energy, and heat reuse must be submitted to a centralized database of the European Commission.
These obligations, applicable since June 2024 in all member states, concern both enterprise data centers and colocation sites. No exemptions are provided based on the ownership model. The first reporting campaign covered the year 2023, with annual deadlines set in the spring.
For companies operating on-site clusters, this means documented monitoring of consumption by node and by rack. The architecture of the cluster, the choice of cooling, and the density of servers become audited parameters, not just internal technical decisions. Understanding the definition of a cluster in computing now requires integrating this regulatory dimension from the design phase.
Nodes, network, and resource manager: anatomy of a cluster
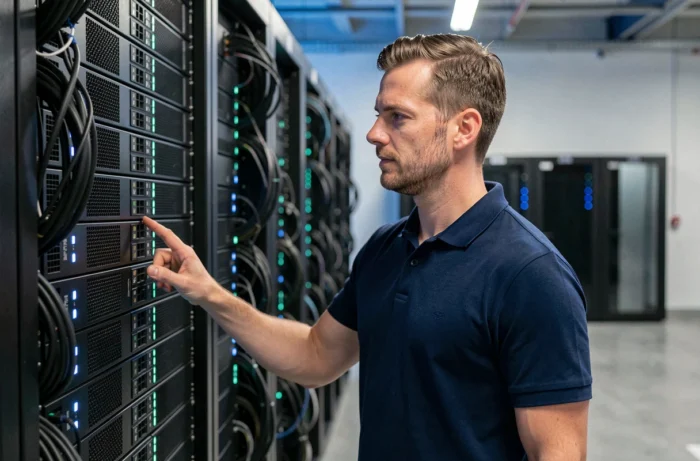
A cluster consists of nodes (physical or virtual servers), a high-speed interconnection network, and management software that orchestrates task distribution. Each node has its own operating system and its processor, memory, and storage resources.
The resource manager distributes workloads among the nodes according to rules configured by the administrator. If a node fails, the system redistributes its tasks to the remaining nodes. This automatic failover mechanism distinguishes a cluster from a simple group of independent servers.
Three common configurations
- High availability cluster: backup nodes take over in case of the main node’s failure. The goal is to reduce service interruptions to a few seconds or less.
- High-performance computing (HPC) cluster: nodes process calculations in parallel to accelerate heavy operations, scientific modeling, 3D rendering, or training artificial intelligence models.
- Distributed storage cluster: data is spread and replicated across multiple nodes. The loss of a disk or server does not result in any data loss.
These configurations are not exclusive. The same cluster can combine high availability and distributed storage according to the company’s needs.
Physical, cloud, or hybrid cluster: concrete trade-offs for companies
The choice between an on-site cluster (bare metal), a cloud cluster, or a hybrid architecture depends on several factors that typical comparisons oversimplify.
A physical cluster offers total control over hardware, network latency, and data security. However, it requires a high initial investment and a team capable of managing the hardware, firmware updates, and the replacement of failing components. The maintenance cost is often the most underestimated burden in on-site cluster projects.
Major cloud providers offer preconfigured clusters with automatic scaling. The company pays for usage and does not have to manage the hardware. Field feedback varies on this point: some companies find that cloud costs exceed those of a physical cluster beyond a certain volume of constant usage, while others find net savings due to elasticity.
The hybrid approach, which combines a local cluster for predictable workloads and cloud resources to absorb peaks, is gaining traction. It raises orchestration questions: the resource manager must coordinate nodes with very different latencies, complicating configuration and debugging.
Kubernetes and container orchestration: the reimagined cluster
The rise of Kubernetes has changed how companies design their clusters. Instead of deploying applications directly on servers, they package them into containers managed by an orchestrator.
Kubernetes breaks the cluster into worker nodes controlled by a control plane. The orchestrator decides where to place each container based on available resources, automatically restarts failing containers, and manages scaling.
This layer of abstraction provides flexibility but adds its own complexity. Securing a Kubernetes cluster requires skills distinct from traditional system administration. Network policies between containers, secret management, and API access control for the cluster constitute attack surfaces that teams must cover.
When Kubernetes is not the answer
For a low-latency HPC computing cluster, Kubernetes introduces overhead that can degrade performance. Simulation or modeling applications that require ultra-fast communication between nodes often remain deployed on traditional HPC clusters with specialized interconnections (InfiniBand, for example).
The choice of orchestration layer thus depends on the type of workload. A high-traffic web cluster and a scientific computing cluster have neither the same architecture nor the same manager.
European performance label: a constraint to anticipate
Beyond the annual reporting already in effect, the European Commission is working on a mandatory sustainability label for data centers, comparable to energy labels for household appliances. This project, based on Article 33 of the Energy Efficiency Directive, targets installations with an installed IT power exceeding 500 kW.
The available data does not allow for a conclusion about the exact implementation date, but discussions foresee a timeline around 2027. For companies sizing a cluster today, integrating energy efficiency criteria into the specifications now avoids future compliance costs.
The architecture of a cluster is no longer just a matter of computing power and redundancy. The European regulatory framework also makes it a matter of energy compliance, which redistributes priorities in infrastructure decisions.